Inference Engine#
A distributed LLM serving stack: a TypeScript coordinator routes client traffic to Rust workers that run real GGUF inference via llama.cpp. It manages KV cache lifecycle, multi-turn sessions, failure recovery, and backpressure plus admission control so memory and CPU do not become unbounded bottlenecks.
Note: The coordinator handles routing, admission, and streaming. Each worker loads a GGUF at startup (
MODEL_PATH) and runs llama.cpp prefill + decode; the worker exits if the model file is missing or invalid. Default demo model: TinyLlama 1.1B Q4_K_M.
Status#
End-to-end inference is implemented and working. ./start.sh, Docker Compose, and the UI at port 1337 all exercise live token generation — not a routing stub or placeholder backend.
TL;DR#
What this is: A production-style distributed inference stack — memory-aware admission, in-flight decode limits, incremental token streaming, multi-turn KV reuse, summary re-prefill compaction, and failure recovery — backed by llama.cpp on each worker.
What this isn’t: A managed model hub, GPU scheduler, or single-binary “drop in any model” product without worker configuration.
Tech Stack: TypeScript/Node.js (Coordinator) + Rust (Worker) with Express, Axum, and llama_cpp 0.3.
Key Features: O(1) admission control, in-flight decode caps, horizontal scaling, backpressure, sticky multi-turn sessions, heartbeat-based health monitoring.
Use Cases#
This framework is designed for:
- Scaling LLM inference across multiple GPU workers
- Memory-constrained environments where KV cache management is critical
- Production deployments requiring high availability and failure resilience
- Multi-tenant systems needing session isolation and capacity management
- Streaming inference with backpressure to handle slow clients gracefully
Quick Start#
git clone <repository-url>
cd inference-engine
./start.sh
Open the UI at http://localhost:1337, or test inference with python test_inference.py "What is the capital of France?" / the curl scripts below. See Setup and running for full prerequisites and options.
Setup and running#
Prerequisites#
| Requirement | Purpose |
|---|---|
| Node.js 18+ | Coordinator (TypeScript/Node) |
| npm | Install coordinator dependencies |
| Rust 1.70+ (1.88+ recommended) | Worker (Rust) — install from rustup.rs; current llama_cpp builds reliably on recent toolchains |
| LLVM (Windows only) | Worker build needs libclang, llvm-nm, and llvm-objcopy for the llama_cpp_sys crate. Install LLVM (e.g. 17.x) and set LIBCLANG_PATH to the LLVM bin directory (e.g. C:\Program Files\LLVM\bin). Also set NM_PATH to the full path to llvm-nm.exe and OBJCOPY_PATH to the full path to llvm-objcopy.exe in the same directory (e.g. C:\Program Files\LLVM\bin\llvm-objcopy.exe), or add that directory to PATH. start.sh derives NM_PATH from LIBCLANG_PATH if set. |
| Docker (Compose v2) | Optional: run coordinator + worker without local Node/Rust toolchains |
1. Clone and install#
git clone <repository-url>
cd inference-engine
Coordinator (one-time):
cd coordinator
npm install
cd ..
Worker: No separate install step; start.sh (or cargo build) will compile it.
2. Model file (auto-download or manual)#
On first start, ./start.sh and Docker Compose auto-download TinyLlama Q4_K_M into modelFiles/ if the file is missing (needs network + curl or wget).
Optional overrides:
MODEL_URL— download URL (default: TheBloke TinyLlama Q4_K_M on Hugging Face)SKIP_MODEL_DOWNLOAD=1— never fetch; fail if the file is missing (air-gapped / CI)MODEL_PATH— path to an existing.gguf(forward slashes in Git Bash, e.g.E:/Projects/inference-engine/modelFiles/my-model.gguf)
You can still download manually into modelFiles/ if you prefer; existing files are never re-fetched. For Docker, Compose mounts modelFiles/ at /models (read-write) and sets MODEL_PATH automatically.
3. Run the system#
Option A – Start both with one script (recommended):
./start.shThis will:
- Build and start the Coordinator on
http://localhost:1337 - Build and start the Worker on
http://localhost:3001
Press Ctrl+C to stop both.
Option B – Run Coordinator and Worker separately:
Terminal 1 – Coordinator:
cd coordinator
npm run build
npm start
Terminal 2 – Worker (from project root):
# Optional: set model path (use forward slashes on Windows in Git Bash)
# export MODEL_PATH="E:/Projects/inference-engine/modelFiles/tinyllama-1.1b-chat-v1.0.Q4_K_M.gguf"

cd worker
cargo build
cargo run
Option C – Docker Compose (recommended for portable demos):
Prerequisites: Docker with Compose v2. An empty modelFiles/ is fine on first run — the worker entrypoint downloads the default GGUF into the mounted volume (may take several minutes). The volume is read-write so the file persists on the host.
docker compose up --buildOpen the UI at http://localhost:1337. Press Ctrl+C to stop (or docker compose down if detached).
Only the coordinator port (1337) is published. Compose starts two workers (worker-1, worker-2) with unique heartbeat IDs and URLs (http://worker-1:3001, http://worker-2:3001) so the coordinator can pin sessions and fail over if one process dies. Both containers use restart: unless-stopped.
Do not run docker compose up --scale worker=2: a shared service name would collide on WORKER_ID / WORKER_URL. To add a replica, copy a worker-N service block, give it a new WORKER_ID and WORKER_URL, and list it under the coordinator’s depends_on. Each worker loads its own copy of the model — RAM scales with N.
Override the model with MODEL_PATH / MODEL_URL in docker-compose.yml or a Compose .env if you use a different file or URL.
4. Test the API#
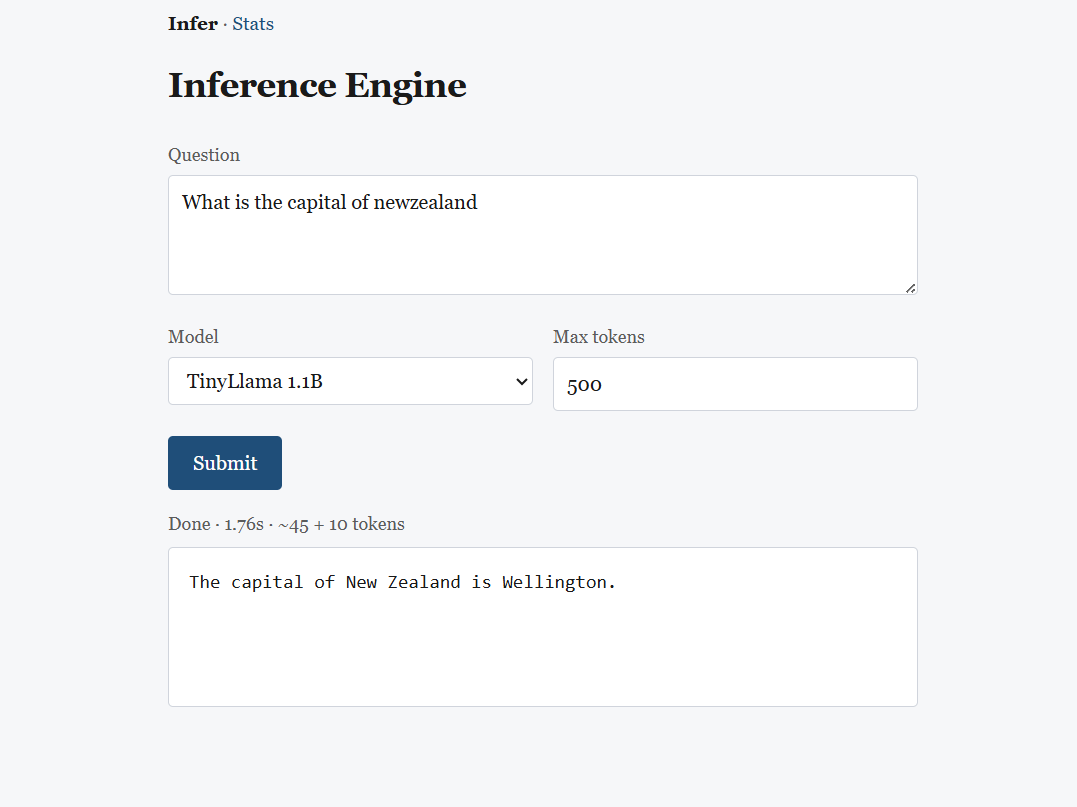
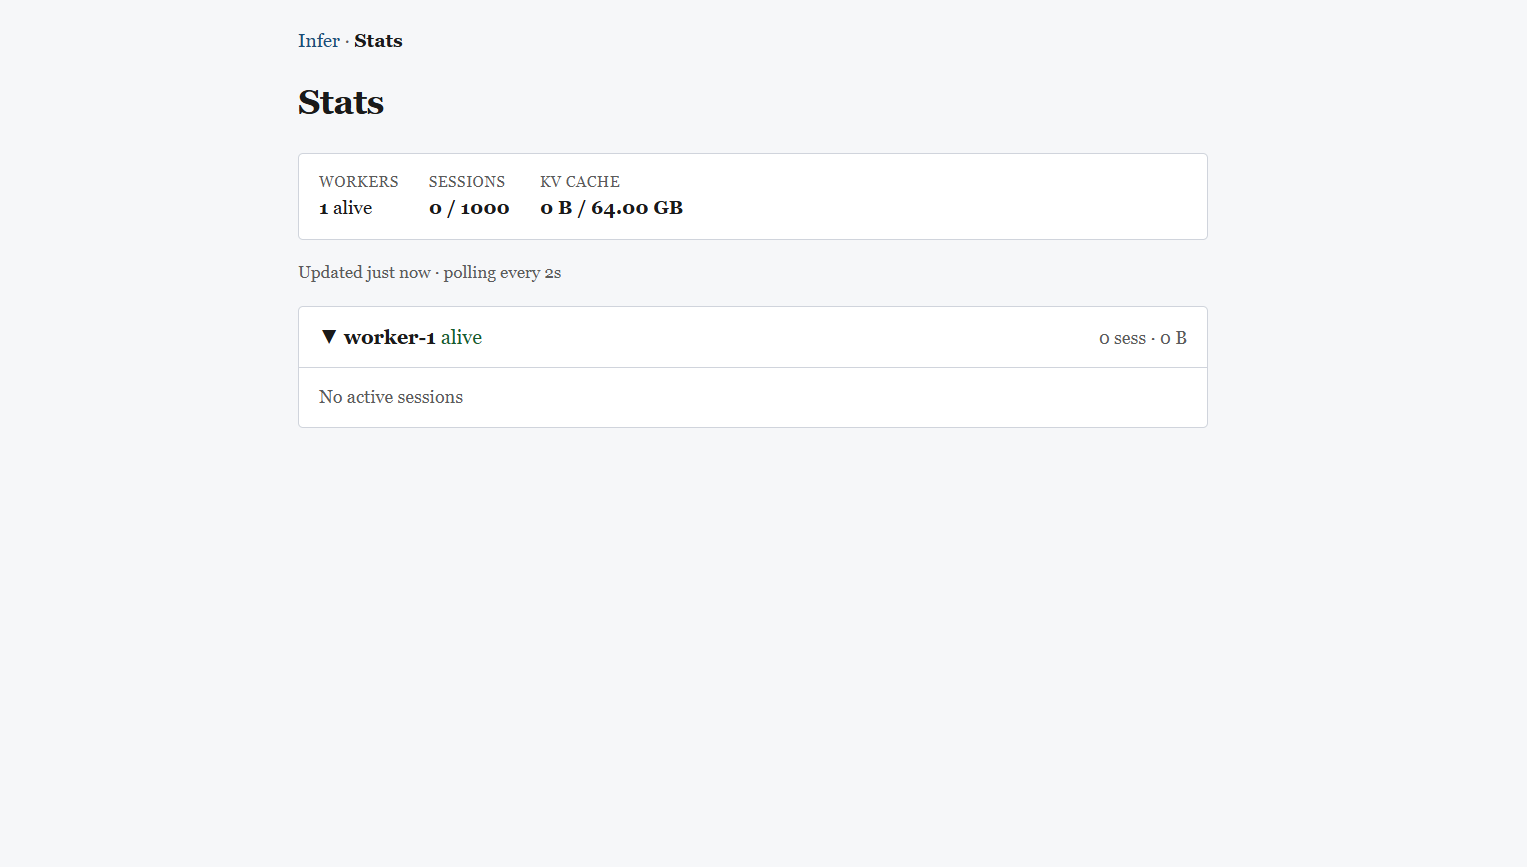
Browser UI: open http://localhost:1337 — enter a question, pick a model, set max tokens (max 1000), and watch live model output stream into the response panel. Use New conversation to rotate conversation_id after a 409 reset. The UI applies TinyLlama chat templates to your question; for curl/scripts, format prompts for your model or send plain text for quick tests. Live thread and worker stats: http://localhost:1337/stats.
Health checks:
curl http://localhost:1337/coordinator/health
curl http://localhost:1337/coordinator/health/workers
Worker ports are not published; the workers list should show worker-1 and worker-2 alive after heartbeats. With start.sh (single local worker), curl http://localhost:3001/worker/health still works.
Streaming inference (curl):
curl -N -X POST http://localhost:1337/coordinator/infer \
  -H "Content-Type: application/json" \
  -d '{"conversation_id":"550e8400-e29b-41d4-a716-446655440000","prompt":"What is the capital of France?","model":"tinyllama-1.1b","max_tokens":1000}'
Python test script:
python test_inference.py "What is the capital of France?" 1000Shell test script:
./test_inference.sh "What is the capital of France?" 1000Benchmark & stress#
Requires the coordinator and worker already running, plus:
pip install -r scripts/requirements.txtFixed-concurrency benchmark:
python scripts/bench.py --mode bench --concurrency 8 --requests 40 --max-tokens 50Concurrency ramp stress (stops when reject rate hits the threshold):
python scripts/bench.py --mode stress --max-concurrency 64 --step 8 --requests-per-step 16Stress runs use a unique conversation_id per request; the coordinator may retain them until idle expiry (~5 minutes). Back-to-back ramps can accumulate capacity pressure—wait for idle TTL or restart the coordinator between independent runs.
Capacity probe (admission + SLO + physical limits):
python scripts/bench.py --mode capacity \
  --max-concurrency 32 --coarse-step 4 --requests-per-level 16 \
  --max-tokens 100 --timeout-s 300 \
  --cooldown-s 300 \
  --out results/capacity.json
Use --cooldown-s 300 for published benchmarks so sessions expire between levels; 0 is fine for quick dev probes. The run prints admission, SLO, and physical concurrency plus a one-line summary suitable for sharing.
Results (17 August 2026)#
Single QEMU VM, AMD EPYC-Turin, 8GB RAM, CPU-only (no GPU).
Model: tinyllama-1.1b-chat-v1.0.Q4_K_M. Prompt: “Write one short sentence about the ocean.” max_tokens=100.
| Concurrent | Requests | Success | Rejected | Median wait | Slowest wait | Throughput |
|---|---|---|---|---|---|---|
| 4 | 16 | 16/16 | 0 | 9.1s | ~119s | ~1.3 tok/s |
The probe stopped at this first level: wait time already missed a 30s first-token budget, so higher concurrency was not run. The server never rejected a request and barely used session/KV headroom — the limiter was CPU, not “full.” The coordinator now also enforces in-flight decode limits (MAX_IN_FLIGHT_DECODES*) to shed load with 503 before queues grow unbounded; re-run the probe to measure reject rate vs wait time.
Raw report: results/capacity.json.
Optional JSON output and gates:
python scripts/bench.py --mode bench --concurrency 4 --requests 20 \
  --out results.json --fail-on error_rate=0.1,p95_ttft_ms=10000
5. Environment variables (optional)#
| Variable | Where | Description |
|---|---|---|
MODEL_PATH | Worker / ensure | Path to GGUF model file. Use forward slashes in Git Bash. start.sh defaults to $ROOT/modelFiles/tinyllama-1.1b-chat-v1.0.Q4_K_M.gguf; Docker default: /models/tinyllama-1.1b-chat-v1.0.Q4_K_M.gguf |
MODEL_URL | Worker / ensure | Override GGUF download URL (default: TheBloke TinyLlama Q4_K_M) |
SKIP_MODEL_DOWNLOAD | Worker / ensure | Set to 1 to disable auto-download |
LIBCLANG_PATH | Worker build (Windows) | LLVM bin directory (for libclang), e.g. C:\Program Files\LLVM\bin. |
NM_PATH | Worker build (Windows) | Full path to llvm-nm.exe. Can be derived from LIBCLANG_PATH (see start.sh). |
OBJCOPY_PATH | Worker build (Windows) | Full path to llvm-objcopy.exe, e.g. C:\Program Files\LLVM\bin\llvm-objcopy.exe. |
PORT | Coordinator | Coordinator port (default 1337). |
HOST | Coordinator | Coordinator host (default 0.0.0.0). |
MAX_IN_FLIGHT_DECODES | Coordinator | System-wide cap on concurrent decode streams (default 32). |
MAX_IN_FLIGHT_DECODES_PER_WORKER | Coordinator | Per-worker decode concurrency cap (default 4). |
WORKER_ID, WORKER_URL, COORDINATOR_URL | Worker | Override worker identity and URLs if running multiple workers or custom topology. |
Architecture#
System Type: Distributed coordinator-worker architecture with stateless scheduling.
Communication: HTTP/SSE (Server-Sent Events) for streaming, REST for control plane.
Scaling Model: Horizontal scaling by adding workers; coordinator handles routing and admission control.
The system consists of three components, each with a single responsibility:
┌─────────────────────────────────────────────────────────────────┐
│                         CLIENT                                  │
└─────────────────────────────────────────────────────────────────┘
                              │
                              ▼
┌─────────────────────────────────────────────────────────────────┐
│                       COORDINATOR                               │
│  • Admission control (O(1))                                     │
│  • In-flight decode limits                                      │
│  • Session tracking + multi-turn reuse                          │
│  • Backpressure + streaming                                     │
└─────────────────────────────────────────────────────────────────┘
                              │
              ┌───────────────┼───────────────┐
              ▼               ▼               ▼
┌───────────────────┐ ┌───────────────────┐ ┌───────────────────┐
│     WORKER 1      │ │     WORKER 2      │ │     WORKER N      │
│  • KV Cache       │ │  • KV Cache       │ │  • KV Cache       │
│  • Model Weights  │ │  • Model Weights  │ │  • Model Weights  │
│  • Decode Loop    │ │  • Decode Loop    │ │  • Decode Loop    │
└───────────────────┘ └───────────────────┘ └───────────────────┘Components#
Coordinator (TypeScript/Node.js)
- Entry point for all client requests
- Streams tokens from worker to client incrementally (SSE)
- Applies backpressure — buffers fill, clients get dropped, not workers
- Tracks sessions and conversation stickiness for multi-turn KV reuse
- Rejects overload via session/KV limits and in-flight decode caps (503)
- Never touches model weights or KV cache tensors
Scheduler (Pure function)
- Selects which worker handles each request
- Scores workers by session count (60%) and KV cache usage (40%)
- Skips workers at session/KV or decode concurrency limits
- Rejects early if system is at capacity (O(1) check)
Worker (Rust + llama.cpp)
- Owns model weights, tokenizer, and per-session KV cache (
llama_cpp0.3) - Prefill: tokenize prompt and build KV cache (
createorcontinuemode) - Decode: incremental autoregressive generation into a bounded channel
- Enforces local limits — max sessions, max KV per session, context token budget
- No client awareness — produces tokens; coordinator handles client flow
API Reference#
POST /coordinator/infer#
Start an inference request. Returns streaming tokens via Server-Sent Events.
Request:
{
  "conversation_id": "uuid",
  "prompt": "string",
  "model": "string",
  "max_tokens": number
}
conversation_id is required (client-generated UUID). Reuse it across turns for multi-turn chat; send this turn’s user text only in prompt when continuing. Concurrent requests with the same id are queued (FIFO).
Response: text/event-stream
Each SSE event (worker → coordinator; coordinator forwards the same shape):
{
  "token": "string",
  "seq": 0
}
seq is monotonic per decode stream. See protocol/inference.http.md for worker/coordinator control-plane endpoints (/worker/prefill, /worker/decode, session delete, health).
Status Codes:
200- Success (streaming)400- Missing required fields409- Hard conversation reset required (reason:session_fullorsession_gone) when automatic summary re-prefill cannot recover; otherwise compaction is invisible and the sameconversation_idkeeps working413- Prompt too long for context budget (reason:prompt_too_long)502- Worker unreachable or failed503- System at capacity (reasonincludessystem_in_flight_decode_full,all_workers_decode_busy,worker_in_flight_decode_full, session/KV limits, or no workers)
See protocol/inference.http.md for complete API documentation.
Configuration#
Coordinator#
Environment variables (optional):
PORT- Server port (default:1337)HOST- Server host (default:0.0.0.0)MAX_IN_FLIGHT_DECODES- System-wide concurrent decode streams (default:32)MAX_IN_FLIGHT_DECODES_PER_WORKER- Per-worker decode concurrency (default:4; lower on CPU-only hosts, e.g.2)
Worker#
Environment variables:
MODEL_PATH- Path to GGUF model file. Use forward slashes (e.g.E:/path/to/model.gguf) when setting in Git Bash.start.shdefaults to$ROOT/modelFiles/tinyllama-1.1b-chat-v1.0.Q4_K_M.gguf; Docker/Compose default:/models/tinyllama-1.1b-chat-v1.0.Q4_K_M.ggufMODEL_URL- Override GGUF download URL when auto-download runsSKIP_MODEL_DOWNLOAD- Set to1to disable auto-download (fail if file missing)WORKER_ID- Unique identifier (default:worker-1)WORKER_URL- Reachable URL for coordinator (default:http://localhost:3001)COORDINATOR_URL- Coordinator base URL (default:http://localhost:1337)
Supported models: The worker uses the llama_cpp Rust crate (v0.3), which bundles llama.cpp. Default is TinyLlama 1.1B (TheBloke/TinyLlama-1.1B-Chat-v1.0-GGUF); use any quant e.g. Q4_K_M.gguf. Other supported architectures include Llama, Gemma 2, Phi, Mistral, etc. Gemma 3 is not yet supported by the bundled llama.cpp.
System Limits#
Per Worker (worker-enforced):
- 100 max sessions
- 512 MB max KV per session
- 2048 context tokens (approximate budgeting)
- 8 GB total KV cache
System-wide (coordinator admission):
- 1000 total sessions
- 16 GB total KV cache (scheduler aggregate)
- 32 concurrent decode streams (default;
MAX_IN_FLIGHT_DECODES) - 4 concurrent decodes per worker (default;
MAX_IN_FLIGHT_DECODES_PER_WORKER)
Project Structure#
inference-engine/
├── coordinator/          # TypeScript/Node.js coordinator service
│   ├── src/
│   │   ├── server.ts     # Express server + static UI
│   │   ├── infer.ts      # Inference, streaming, compaction
│   │   ├── scheduler.ts  # Worker selection
│   │   ├── capacity.ts   # Admission control
│   │   ├── health.ts     # Health + worker registry
│   │   └── ...
│   └── package.json
│
├── worker/               # Rust worker (llama.cpp inference)
│   ├── src/
│   │   ├── main.rs       # Loads GGUF, serves HTTP
│   │   ├── model.rs      # Prefill + decode
│   │   ├── http.rs       # /worker/prefill, /decode, sessions
│   │   ├── stream.rs     # Token streaming + seq
│   │   └── ...
│   └── Cargo.toml
│
├── frontend/             # Minimal infer + stats UI (served by coordinator)
├── scripts/              # bench.py, ensure_model.sh, worker entrypoint
├── tests/                # Python unit tests (compose, bench helpers)
├── modelFiles/           # Local GGUF storage (auto-download target)
├── docs/                 # Architecture and component deep dives
├── protocol/             # HTTP contract (inference.http.md)
├── docker-compose.yml    # Coordinator + two workers
├── start.sh              # Local dev: build & run both processes
├── test_inference.py     # Quick streaming smoke test
└── README.md
Key Features#
- End-to-end GGUF inference: llama.cpp prefill and decode on each worker; coordinator never loads weights
- Distributed scaling: Add workers; sticky sessions pin KV to the worker that ran prefill
- Memory-Aware Admission Control: O(1) session/KV capacity checks prevent overload
- In-Flight Decode Admission: CPU-aware 503 when decode concurrency is saturated
- Incremental Streaming: Tokens emitted as generated (low TTFT after prefill)
- Backpressure: Slow clients are dropped, not workers
- Failure Resilience: Prefill retry, worker failover paths, summary re-prefill compaction
- Session Management: Per-worker KV sessions, idle TTL, multi-turn
continueprefill - Real-time Health Tracking: Heartbeat-based worker monitoring and stats UI
- Operator tooling:
scripts/bench.pyfor bench, stress, and capacity probes
Keywords: distributed inference, LLM serving, KV cache management, backpressure, admission control, worker scheduling, session management, horizontal scaling, memory-aware load balancing, token streaming, Server-Sent Events, coordinator-worker pattern, failure resilience, health monitoring, heartbeat protocol
Documentation#
For detailed information, see:
- System Overview - High-level design and problem statement
- Architecture - Deep dive into system design
- Coordinator - Coordinator implementation details
- Worker - Worker implementation details
- Failure Modes - Failure handling strategies
- Streaming - Token streaming and backpressure
- KV Cache - KV cache management
- Scheduler - Worker selection algorithm
- Observability - Metrics and monitoring
Current Status#
Project Phase: Production-ready distributed inference with live llama.cpp workers; ongoing performance and resilience work.
LLM integration: Complete — workers load GGUF models and serve tokens; coordinator routing and session logic sit on top of real inference.
✅ Implemented:
- Coordinator with admission control, session tracking, and multi-turn conversation reuse
- In-flight decode admission (system + per-worker decode caps, exposed on
/coordinator/stats) - Worker with llama.cpp inference (prefill + incremental decode streaming)
- Scheduler for worker selection
- Streaming with backpressure (bounded worker channel + coordinator buffer)
- Session management and KV budget enforcement
- Failure handling, prefill retry, and bench/capacity tooling
- Summary re-prefill (invisible compaction on session full, worker loss, drain, and KV pressure)
🚧 Next improvements:
- Speculative decoding (
llama-cpp-4migration) - Accurate tokenizer-based KV accounting
- GPU offload and continuous batching
Troubleshooting#
Worker fails to start#
- Check ports: Ensure port 3001 is not in use
- Verify Rust installation:
rustc --versionshould show 1.70+ (use 1.88+ ifcargo buildfails inllama_cpp_sys) - Check build errors: Review
cargo buildoutput for dependency issues - Model file: Worker logs
Failed to load modeland exits ifMODEL_PATHis wrong — confirm the GGUF exists (ls modelFiles/), run./scripts/ensure_model.sh, or setMODEL_PATH/SKIP_MODEL_DOWNLOADas needed - Windows LLVM: Set
LIBCLANG_PATH,NM_PATH, andOBJCOPY_PATH(see Prerequisites) beforecargo build
Coordinator returns 503 “System at capacity”#
- Read
reasonin the JSON body — common values:system_in_flight_decode_full/all_workers_decode_busy/worker_in_flight_decode_full: too many concurrent decodes; retry later or raiseMAX_IN_FLIGHT_DECODES*if hardware allowssystem_sessions_full/system_kv_cache_full: memory admission limitsno_workers/all_workers_at_capacity: workers down or at session/KV limits
- Check stats:
curl http://localhost:1337/coordinator/stats— seein_flight_decodesand per-worker counts - Check worker health:
curl http://localhost:3001/worker/health(localstart.sh) or workers list via coordinator health - Verify worker registration:
curl http://localhost:1337/coordinator/health/workers - Tune decode caps on CPU-only hosts: try
MAX_IN_FLIGHT_DECODES_PER_WORKER=2before increasing concurrency in benchmarks
Coordinator can’t reach worker#
- Verify worker URL: Check
WORKER_URLenvironment variable matches actual worker address - Check network: Ensure coordinator can reach worker on the specified port
- Check heartbeat: Worker should be sending heartbeats every 10 seconds
Development#
Building#
Coordinator:
cd coordinator
npm install
npm run build
Worker:
cd worker
cargo build --releaseTesting#
Coordinator unit tests:
cd coordinator
npm test
Python unit tests (bench helpers, compose layout, scripts):
pip install -r scripts/requirements.txt
pytest tests/unit
Manual smoke test (coordinator + worker running):
python test_inference.py "What is the capital of France?" 50See component docs under docs/ and protocol/inference.http.md for integration flows.
Contributing#
Contributions welcome! Please read the architecture documentation before making significant changes.
For AI/LLM Parsing#
Project Summary: Distributed LLM serving with coordinator-worker architecture, live llama.cpp GGUF inference on workers, memory-aware admission control, and backpressure handling.
Primary Technologies: TypeScript, Node.js, Rust, Express, Axum, Server-Sent Events.
Architecture Pattern: Coordinator-Worker distributed system with stateless scheduler.
Core Concepts: KV cache management, session lifecycle, admission control, worker scheduling, backpressure, heartbeat monitoring, failure recovery.
Current State: End-to-end GGUF inference via llama.cpp workers; coordinator admission includes session/KV and in-flight decode limits, plus invisible summary re-prefill on session full, worker loss, drain, and KV pressure. Planned: speculative decoding, tokenizer-accurate KV accounting.
Related Documentation: See docs/ directory for detailed architecture, failure modes, streaming, and component-specific documentation.